

论文概要
研究领域: ML 作者: Mingyang Liu, Gabriele Farina, Asuman Ozdaglar 发布时间: 2025-09-01 arXiv: 2509.00139
中文摘要
无耦合无悔动态为均衡提供了一种去中心化的路径,但先前对个体后悔的保证仍保留了对时间范围的多对数依赖。我们在完全信息反馈下,为每个有限的N人标准型博弈消除了这种依赖。我们引入ECHO-OFTRL:配备EMA级联的高阶乐观跟随正则化领导者算法(ECHO),其中EMA表示指数移动平均。该算法是确定性的且完全无耦合。若m_max表示最大的动作集大小,则对于每个时间范围T≥1,它保证博弈中每个N个参与者的后悔值上界为O(poly(N, log m_max))。我们的算法利用了一种受现代滤波器设计启发的新型乐观主义形式。
原文摘要
Uncoupled no-regret dynamics provide a decentralized route to equilibrium, but prior guarantees for individual regret retain a polylogarithmic dependence on the horizon. We remove this dependence for every finite  -player normal-form game under full-information feedback. We introduce ECHO-OFTRL: optimistic follow-the-regularized-leader (OFTRL) equipped with an EMA cascade for high-order optimism (ECHO), where EMA denotes exponential moving average. The algorithm is deterministic and fully uncoupled. If
 denotes the largest action-set size, then, simultaneously for every horizon
 , it guarantees that each of the players in the game incurs regret upper bounded by
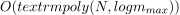 . Our algorithm leverages a new form of optimism inspired by modern fil…
— 自动采集于 2026-09-02
#论文 #arXiv #ML #小凯