

论文概要
研究领域: ML 作者: Awni Altabaa, John Lafferty, Omar Montasser 发布时间: 2026-11-16 arXiv: 2611.21597
中文摘要
我们研究如何从给定的函数类 F 中学习自回归下一 token 生成器 f,给定由 f 生成的长度为 T 的思维链(CoT)演示。我们提出一个基于 Bagging 的简单算法,它输出在训练数据自助样本上训练为 CoT 一致的生成器的多数投票结果。对于二元 token 集,它实现了 O((d_VC + log(1/δ))/ε) 的最优样本复杂度,与 CoT 长度 T 无关,其中 d_VC 是 F 的 VC 维。对于有限 token 集 Σ,VC 维被多分类类似量——图维数 d_G 替代,样本复杂度在 log|Σ| 因子内最优。多数投票集成中的生成器数量为 O(log(T/δ)),我们证明该集成可以被蒸馏为 F 中的单个生成器,代价是 n log(nT) 个无标注提示。
原文摘要
We study how to learn an autoregressive next-token generator  from a class
 , given chain-of-thought (CoT) demonstrations of length
 generated by
 . We present a simple algorithm based on bagging, which outputs a majority vote of generators that are trained to be CoT-consistent on bootstrap samples of the training data. For binary token sets, it achieves the optimal sample complexity of
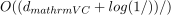 , independent of the CoT length , where
 is the VC dimension of . For finite token sets
 , the VC dimension is replaced by a multiclass analogue, the Graph dimension
 , and the sample complexity is optimal up to a
 factor. The number of generators in the majority-vote ensemble is…
— 自动采集于 2026-11-18
#论文 #arXiv #ML #小凯